Translate

Thursday, January 27, 2022

Indexing : Adding jet fuel to your car

In database technology indexes used to improve the performance of select queries that can be seen from the following figure. 


This post is to show case different cases for indexes using different articles. This article SQL Server Clustered Index Behavior Explained via Execution Plans will tell you how different scenarios are for Clustered Index. 
However, indexes needed to be maintained using rebuild and reorganizing SQL Server Maintenance Plan Index Rebuild and Reorganize Tasks . 
How do we know what is the better index and where the indexes are needed. This can be done Troubleshooting using Wait Stats in SQL Server and specially How to Avoid CXPACKETs? . Another place indexes are Internals of Physical Join Operators (Nested Loops Join, Hash Match Join & Merge Join) in SQL Server .
Column indexes are another important aspect and Script to Create and Update Missing SQL Server Columnstore Indexes.
Furhter we have discussed few more cases for index before at here 
Happy reading into this. 


Thursday, January 13, 2022

Article: Incremental Data Extraction for ETL using Database Snapshots

We have been discussing ETLs in detail for the data warehouse. As you know, in ETL one of the important task is extracting the incremental data extraction from sources. This article discusses a new method to extract data from operational databases and how to use ETL using Database snapshots in order to improve the ETL process.


Thursday, December 23, 2021

What3Words - Expressing Your Location in Three Words

How many times that you had to wait so long for your taxi due to the wrong location? In these pandemic days, how many times has your order is not delivered to your location again due to an invalid location. What3Words is a simple way of expressing your location.


What3words has divided the world into three-meter squares, each with a unique three-word address made from three random words. Now people can refer to any precise location. for example, my location is ///quack.competent.workflow.


You can share the location and another 3-word location for navigating. 3-word addresses are appearing on contact pages, business cards, travel guides and physical signs all around the world. People are using the free what3words app to find friends faster, get accurate directions to that tucked away Airbnb and to drive, or ride, exactly where they want to go.

what3words is available in 40 languages, enabling over 4 billion people to use the system in their native tongue. It can be used via the free mobile app or online map. 

Monday, November 22, 2021

Most Popular Software Programming Languages In Pictures

If you are a developer you might be wondering what is the best language for application development. Let us look at it from some pictures. 


Obviously, JAVA is the winner and you can see C, C++ is also in the higher ranking. However, not sure the reason for the higher ranking on Visual Basic .NET over C#.
Following is the ranking from IEEE. 


JAVA is the non-dispute leader in this ranking as well and it too has the same ranking as previous. The notable observation is the growth of R language over the years. It has jumped to rank 6 from 9. 

Another important parameter is the Salary and Job opening.


Though JAVA has a lot of openings than other programming languages, the average salary is higher in other languages such as Python, C++, Ruby etc.

Finally, let us compare the different aspects of programming languages. 

Thursday, November 18, 2021

Cluster Validation - Purity Calculation

As we know, clustering is an unsupervised technique. When it comes to classification, there are a lot of evaluation techniques such as Precision, Recall, F1, MCC etc. However, what are the techniques that can be used to evaluate clustering techniques. Purity calculation is one of the simplest calculations to evaluate your clusters.

In the Purity cluster quality measure, we will analyse the cluster distribution with respect to a selected variable. Let us look at how to calculate Purity in a Text Clustering using Orange and the following is the Orage flow. 


Further, you can get the Orange flow from Github. 
First, let us look at how the Purity is calculated. 
Let us assume that following are the clusters and data distribution.


In each cluster, the maximum number of objects that are falling to each cluster is calculated. For example, in Cluster 1, X has three instances while Cluster 2 has three instances of O and Cluster 3 has four L instances. Those numbers are added up and divided by the total number of instances which is 16. 

Let us look at this example with our popular film review dataset.

After the text Preprocessing, the Loving Clustering technique is used. Following is the cluster distribution with respect to the review classification.

So the Purity is (190 + 193 + 158 + 123+ 136 + 112+124+102 +11) / 2000. Ideally, this should be close to 1 meanwhile in the case of multi-class we can calculate the Purity with a Minimum value which should be close to 0. 
Entropy is another calculation that is performed to measure the Cluster Quality which we will leave for another day.

Saturday, November 13, 2021

Hasan Ali & Tweets


As they say in Cricket, "Catches win matches". It will be more relevant when you missed a catch in the WorldCup semi-final.  During the T20I world cup when Hasan Ali dropped the catch, the match turned to head to tail. As cricket is a great game of uncertainty, the crowd don't believe in that. After the dropped catch, there were a lot of allegations against Hasan Ali. It went to an extent that his wife and his religion also are part of these allegations. 
Let us analyse tweets against Hasan Ali using Tweet Sentiment Visualization App. 

Though there were a lot of hate comments against Hasan Ali on Facebook, Instagram etc, Twitter users are seems to be more professional as we see a lot of positive tweets against him. Some tweets wishing him success as well. 

When you look at the topics, catch, stay strong are the common topics. 
Then let us look at the Tag Cloud in different quadrants. 


Friday, November 5, 2021

Microsoft SQL Server 2022

After three years, Microsoft is gearing up to release its next version of its flagship database product Microsoft SQL Server which is 2022. As for every new release, obvious question us what are the new features.


You can get more details from the following references.

Announcing SQL Server 2022 preview: Azure-enabled with continued performance and security innovation - Microsoft SQL Server Blog

SQL Server 2022 | Microsoft

What's new in SQL Server 2022 - YouTube

PASS Data Community Summit November 8-12 2021 

SQL Server 2022 integrates with Azure Synapse Link and Azure Purview which will enable its users to drive more insights, predictions, and governance from their data at a higher scale. Cloud integration is enhanced with disaster recovery (DR) to Azure SQL Managed Instance, along with no-ETL (extract, transform, and load) connections to cloud analytics, which allow database administrators to manage their data estates with greater flexibility and minimal impact to the end-user. Performance and scalability are automatically enhanced via built-in query intelligence. There is choice and flexibility across languages and platforms, including Linux, Windows, and Kubernetes.

Thursday, November 4, 2021

Article: Use Replication to improve the ETL process in SQL Server


As we have discussed in many articles, ETL is one of the challenging tasks in a Data Warehouse. It is important to extract data from data sources without impacting the performance of the data sources. in SQL Server, replication can be used to safeguard the performance of data sources during the ETL. Read this article Use Replication to improve the ETL process in SQL Server.

Sunday, October 24, 2021

Federalist Papers : Case for Naïve Bayes Text Classification

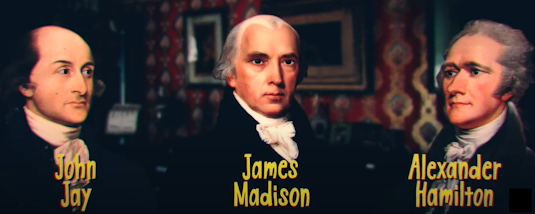
Alexander Hamilton, James Madison, and John Jay

The Federalist Papers is a collection of 85 articles and essays written by Alexander Hamilton, James Madison, and John Jay. 1787 after the UK was thrown out from US, many were in the view that 13 counties should rule independently. 

John Jay, James Madison, Alexander Hamilton wrote letters independently to pursue that the US should have a strong central government with the individual state government. Between 1787 - 1788 these papers were published under the pseudonym PUBLIS. While the authorship of 73 of The Federalist essays is fairly certain, the identities of those who wrote the twelve remaining essays are disputed by some scholars. In 1963 this dispute was fixed by Mosteller and Wallace using Bayesian Methods.

Let us see do a simple analysis of these papers by performing a analyse of the titles of these papers using the Orange Data Mining Tool. You can retrieve the sample files and the Orange workflow from dineshasanka/FederalistPapersOrangeDataMining (github.com). 

Following is the Orange Data Mining workflow and let us go through important controls. 

After importing the CSV, text was preprocessed and word cloud was generated to identify the word distribution. 


Bags of Words are used to identify the keywords. Then six classifiers are used which are Neural Network, Naive Bayes, Decision Trees, Random Forest, SVM and AdaBoost. Following is the evaluation results and it shows that the Random Forest technique has the edge over the other techniques 

We can build the decision tree as shown below. 

Saturday, October 23, 2021

Monitor Your System Metrics With InfluxDB Cloud in Under One Minute

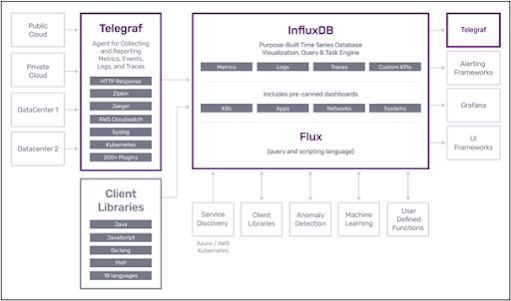
InfluxDB is a Time Series stack that will provide end-to-end features to capture, store and present time series data. 

Following is the InfluxDB 2.0 stack that covers all aspects of time series data.

Influx DB 2.0 stack

Let us see how we can use InfluxDB 2.0 to monitor the operating system. 

First, you need to create a account to FluxDB Could. 

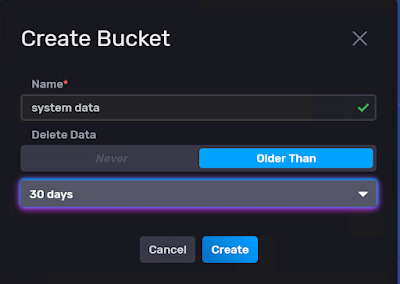
Next is to create a bucket to store the data. 


Creating a Bucket in InfluxDB

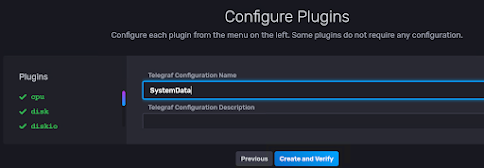
After the bucket is created, you need to configure the plugin from Telegraf. 

Configuring the Plugin

Now you need to set the environment variable and need to execute Telegraf by using the following commands. 


Then you can create a query from the following. 


You can create the graph as below.